Choose what
you run.
Work with GGUF and compatible transformer models. Run local inference with llama.cpp or torch, with optional vLLM and Ollama integrations.
A workspace, with room to experiment.A local AI studio Development preview
Your models. Your data. Your machine.
Run, fine-tune, and explore AI in a native desktop workspace built around you.
Open source Native desktop Locally run
Discover → Train → Connect → Converse
ALL ON YOUR MACHINE01 / THE WORKSPACE
A place for the whole process.
Less switching tools. More making things.
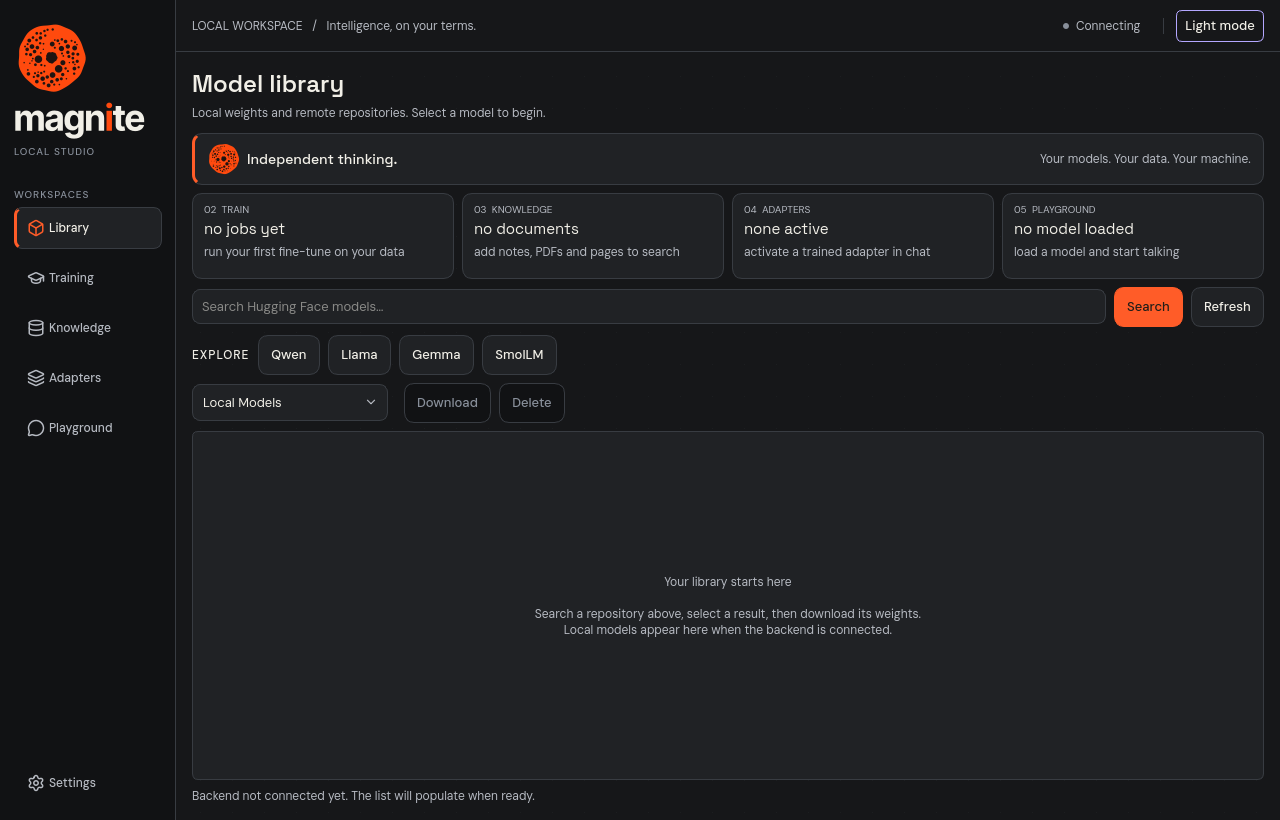
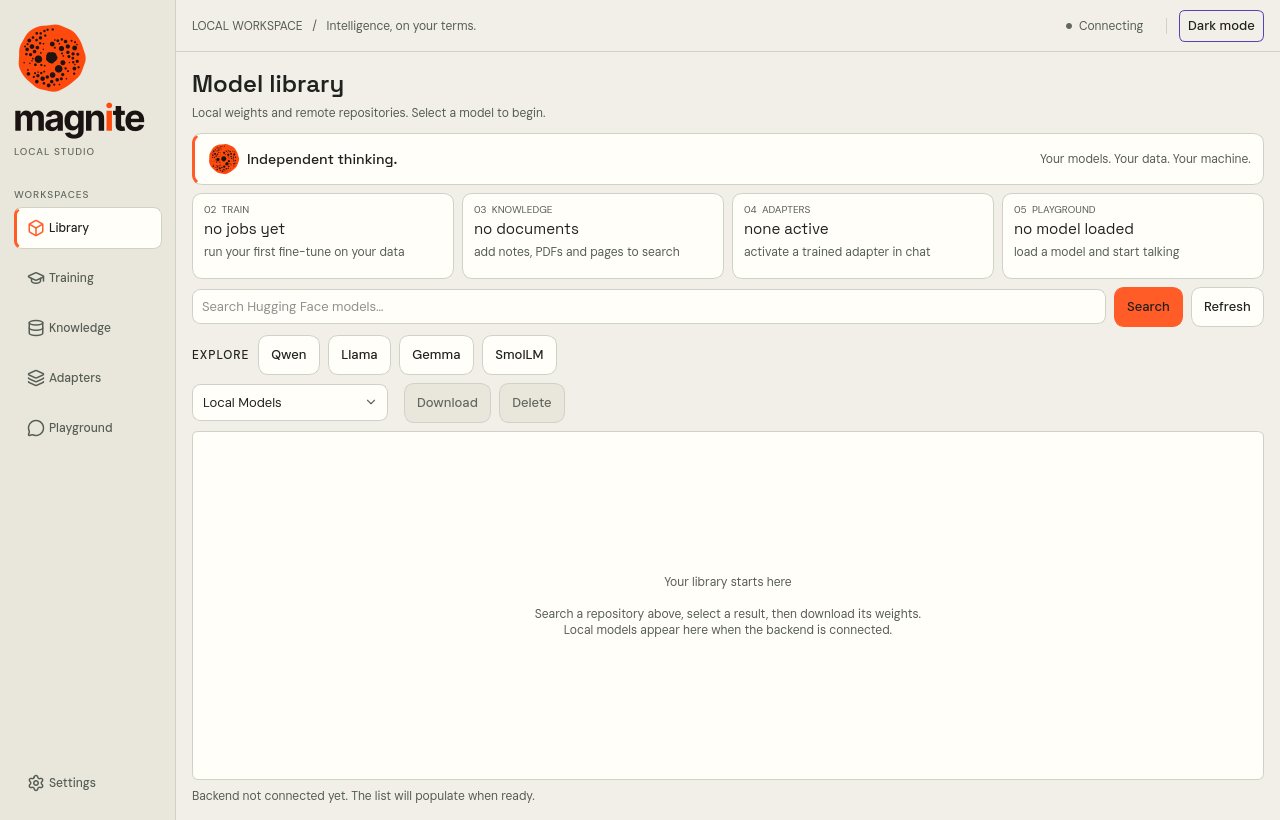
Discover models on Hugging Face, download the weights, and keep your local collection in one place.
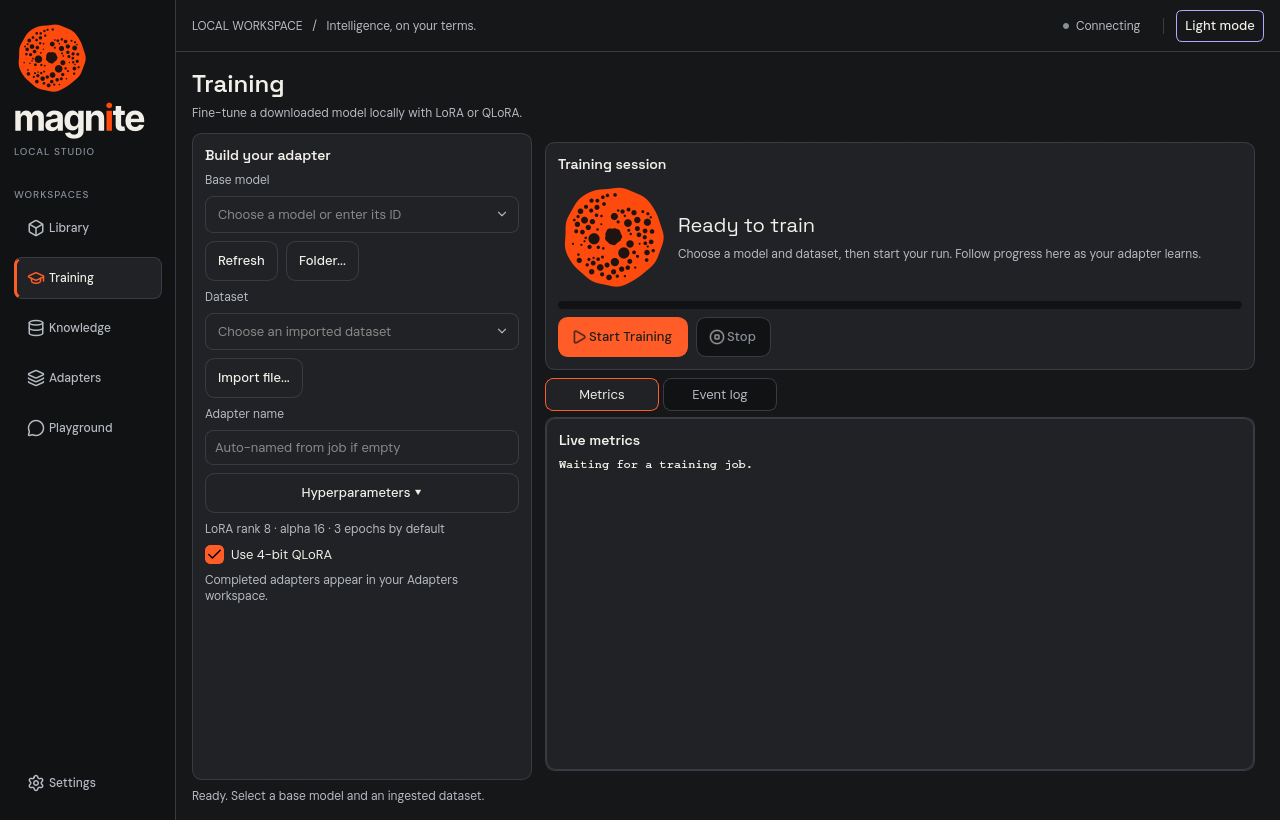
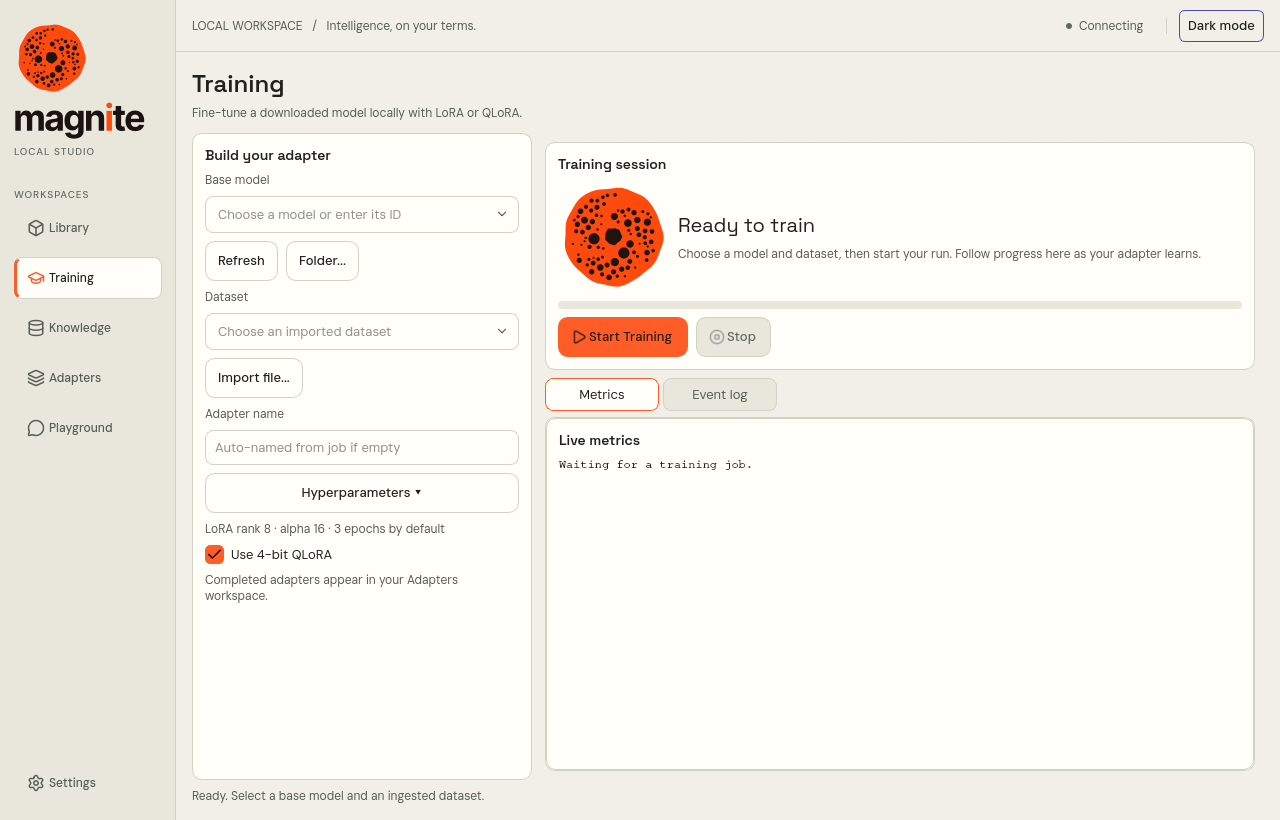
Bring a dataset, configure a LoRA or QLoRA run, and follow your training jobs from the same workspace.
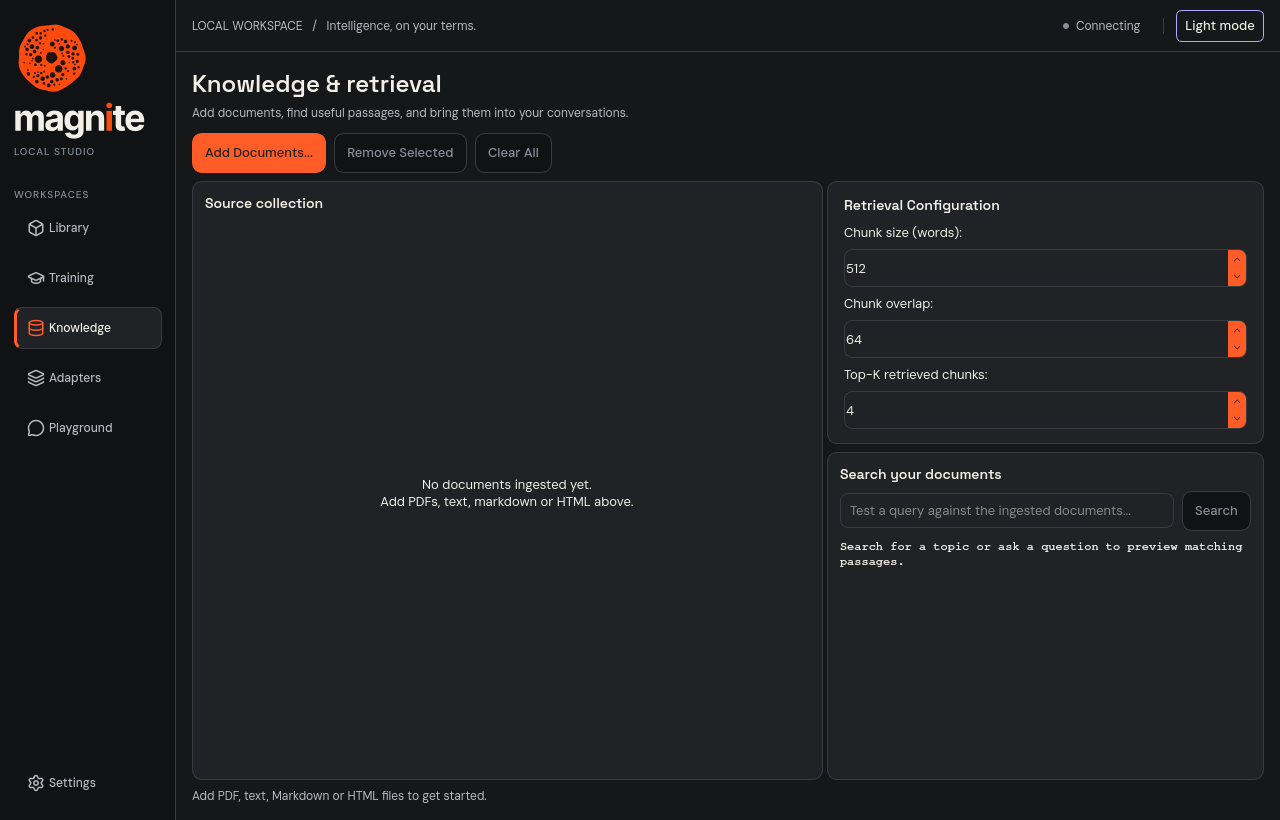
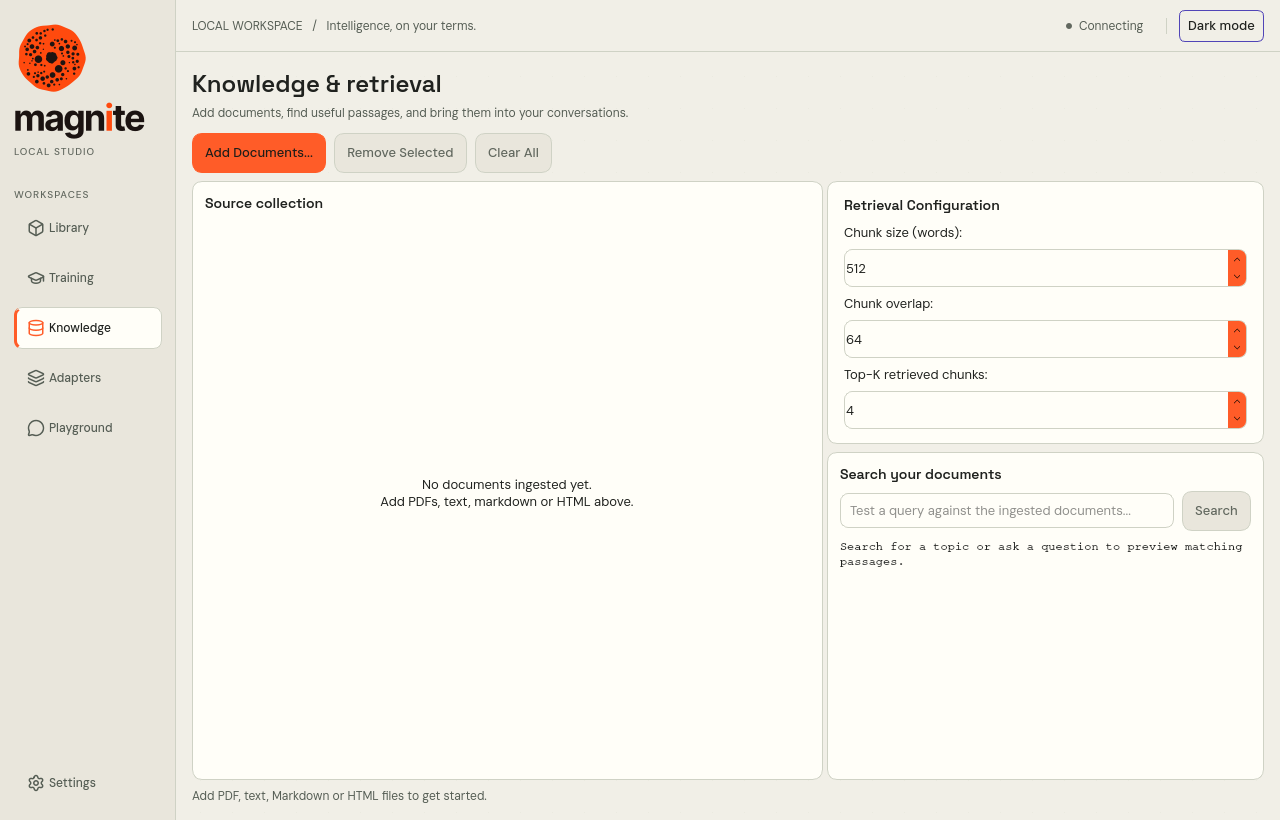
Add PDFs, text, Markdown, or HTML. Retrieve relevant passages and bring your knowledge into the conversation.
Import, export, and activate trained adapters with a compatible base model through the PEFT/torch engine.
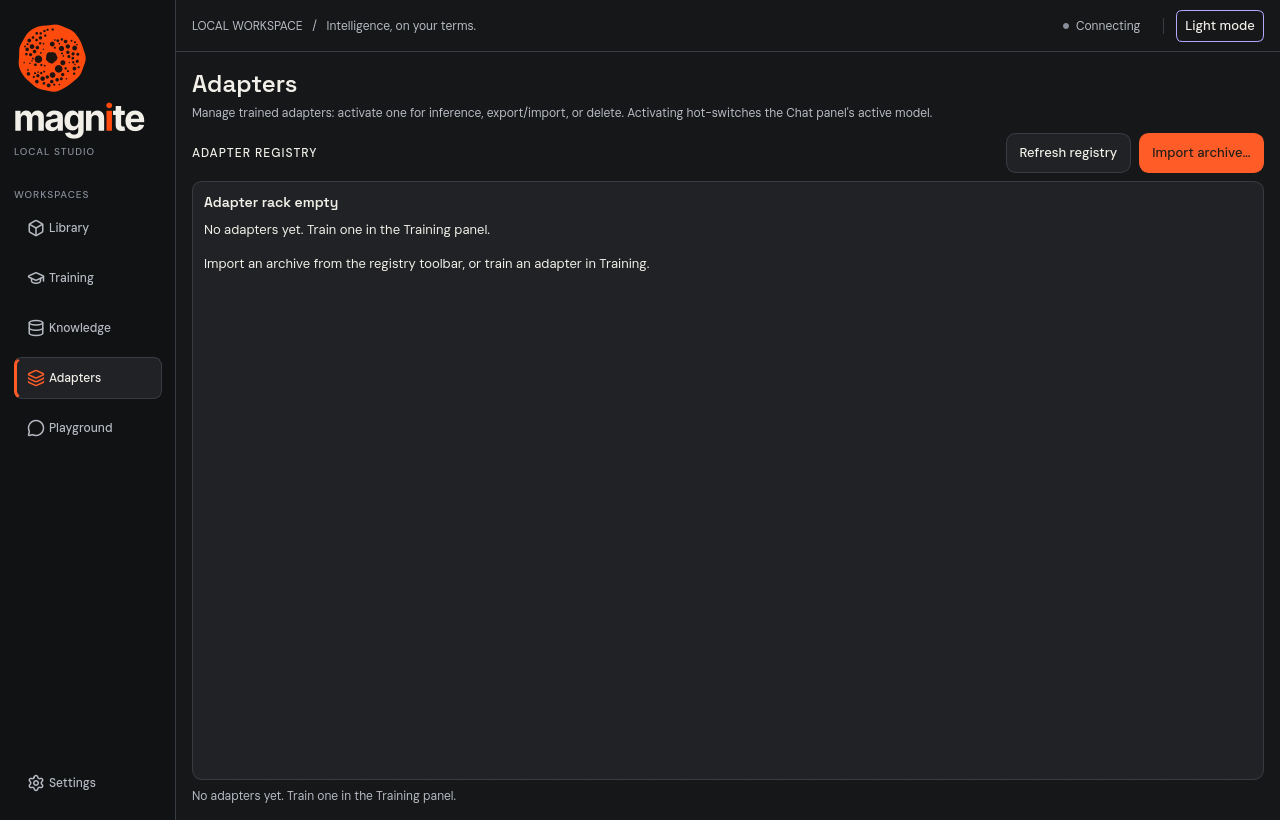
Stream responses from your model, shape its settings, and chat with context from your own documents.
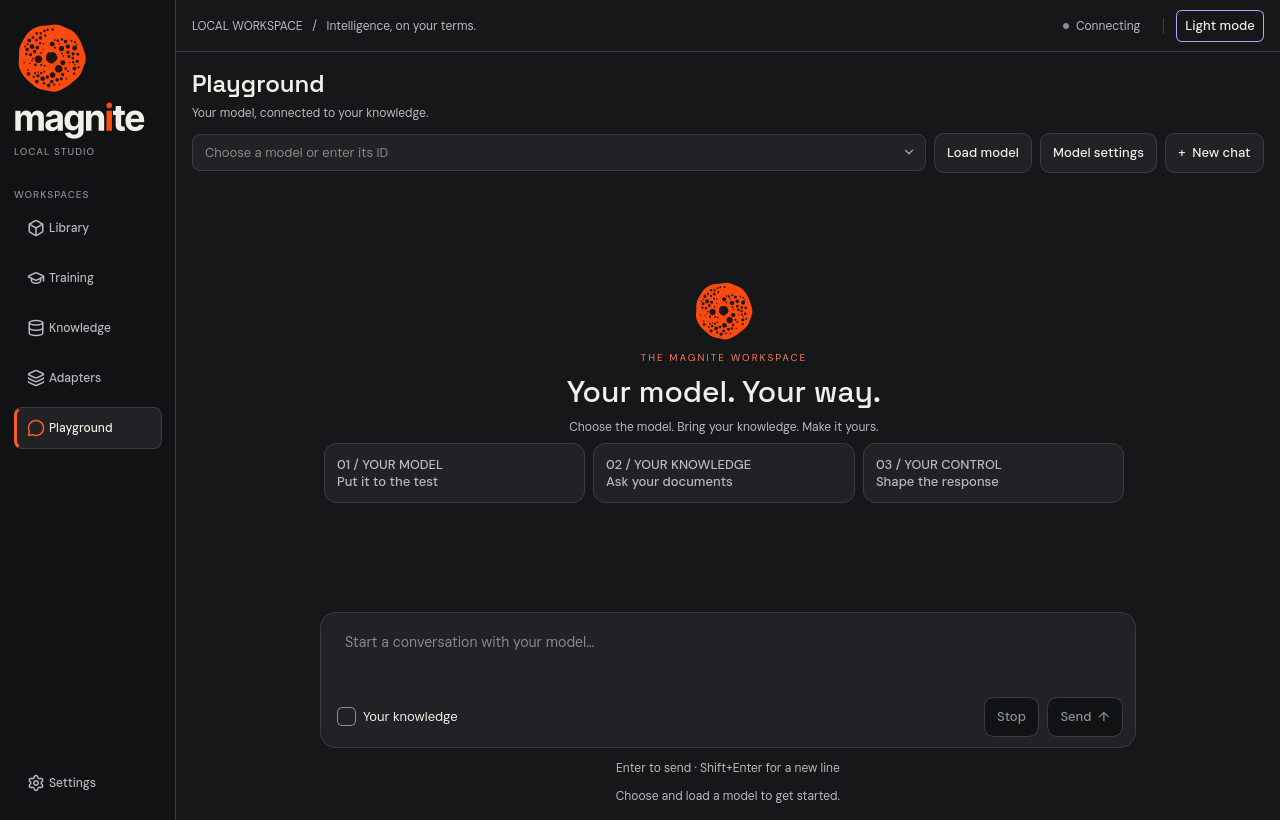
Actual development-preview screens. Workspaces shown before models or documents are added.
02 / WHY LOCAL
Work with GGUF and compatible transformer models. Run local inference with llama.cpp or torch, with optional vLLM and Ollama integrations.
A workspace, with room to experiment.Your datasets, adapters, and documents stay in your local workflow. Training, inference, and document processing run on your machine.
Your knowledge is part of the process.A native Qt desktop app with a local backend and no app telemetry. Once the required weights are cached, local workflows can run offline.
Model downloads need an internet connection.03 / MAKE IT YOURS
Magnite is open source and in active development. Build the preview from source, try a small model, and help shape what comes next.
Linux has development-test evidence. Windows and macOS verification is still pending. QLoRA needs a supported GPU and quantization setup.
git clone https://github.com/Ronit9320/magnite_llm.git
cd magnite_llm
python3 -m venv .venv
source .venv/bin/activate
python -m pip install -e 'backend[ml]'
cmake -S app -B build
cmake --build build -j2
./build/magnite-appA FEW THINGS TO KNOW
It is a development preview. Local training, inference, and document retrieval are the focus. Packaging and release verification are ongoing. Start with small experiments and read the known limitations.
Small GGUF inference and training experiments can run on a CPU with the appropriate dependencies. Larger models need more memory and compute. QLoRA requires supported GPU hardware and bitsandbytes quantization; acceleration depends on your engine build.
Use compatible transformer base weights with JSONL, CSV, or text datasets for LoRA training. GGUF weights are used for inference, rather than ordinary PEFT training. See the workflow guide for supported paths.
Training, inference, and document processing run locally. Hugging Face searches and weight downloads use the internet, and Ollama connects to its configured service URL. Magnite has no application telemetry implementation. See the storage and privacy guide.
Intelligence on your terms.
Make it yours